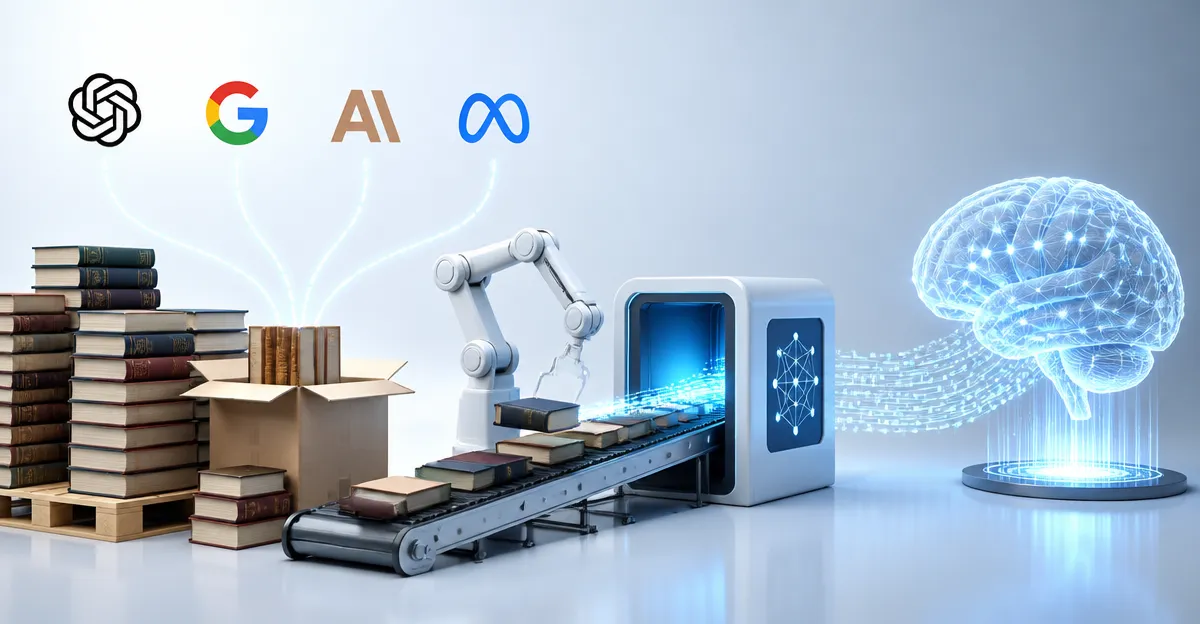
August 4, 2026, (Inside AI) — Anthropic has been systematically buying millions of physical books, destroying their bindings, and scanning the loose pages to train its large language models, newly unsealed court documents confirm. The practice, known as destructive scanning, is part of a broader scramble by AI companies to secure high-quality, human-written text as training data.
Booksellers in Australia and Europe have reported unusual bulk orders from intermediaries, often for rare or out-of-print titles. The Guardian and Fortune documented cases where sellers were unaware the books would be dismantled for AI training. This marks a shift from earlier revelations about Project Panama, Anthropic’s initiative to amass a vast corpus of digitized books, first reported by the Washington Post in January 2026.
The practice is now rippling up the supply chain, with booksellers noticing demand for obscure works. Intermediaries often shield the end buyer, making it difficult to trace how the books will be used. The trend underscores a growing hunger for clean, pre-AI text as web-scraped data becomes increasingly polluted with synthetic content.
Destructive Scanning Fuels Data Hunger
Large language models learn from vast text corpora, and books offer long-form, edited content across diverse subjects. ISBNdb, a company marketing book-sourcing services to AI firms, argues that pre-generative AI books are especially valuable because they lack AI-generated text. As synthetic content proliferates online, older physical books are prized for their purity.
Destructive scanning involves cutting book spines and feeding loose sheets into high-speed scanners. The process yields flat, high-quality images for optical character recognition but permanently destroys the original copy. This contrasts with non-destructive methods used by preservation projects like the Internet Archive, which photographs books without dismantling them.
Chris Freeland, Director of Library Services at the Internet Archive, told the Indian Express that the organization’s 2021 explanation of its scanning process “continues to be the best description of its digitisation process today.” The Archive has long avoided destructive methods to protect brittle or rare volumes.
Yet for AI companies, speed and image quality often outweigh preservation. Many books lack clean digital editions, and publishers tightly control commercial e-book access. Physical copies remain a straightforward, if controversial, path to obtaining training data.
Copyright Gray Zone Expands
The legal landscape is unsettled. Arul George Scaria, professor at the National Law School of India University, described the practice as a middle path between licensing and using shadow libraries. “Buying physical copies and getting them digitised for training appears to be the middle path taken by many AI developers now, as many presume that this is fairer to the authors and publishers,” he said.
Under Indian law, fair dealing exceptions in Section 52 of the Copyright Act of 1957 may apply if digitization is solely for training. But Scaria cautioned that copyright alone may not address author anxieties. He called for solutions beyond law, such as mandatory AI-content labeling and funds for affected creators.
The controversy echoes the Google Books litigation of the 2000s, when Google’s mass digitization project sparked years of copyright battles. Jannis Lennartz, Visiting Professor at Humboldt-Universität zu Berlin, argues in a Verfassungsblog essay that today’s efforts differ in purpose: instead of making books searchable, AI firms convert them into machine-readable training data. This shifts the economics of digitization, treating books as raw material for AI rather than objects of preservation.
Meanwhile, the Internet Archive’s non-destructive approach faces its own legal challenges, including a 2023 ruling that its controlled digital lending program violated copyright. The juxtaposition highlights a deepening divide over how society values physical books in the age of AI.
As the scramble for training data intensifies, the fate of millions of books hangs in the balance. The practice raises urgent questions about cultural preservation, fair use, and the hidden costs of building ever-larger models. For now, booksellers remain on the front lines, often unaware that their sales fuel the destruction of the very works they sell.