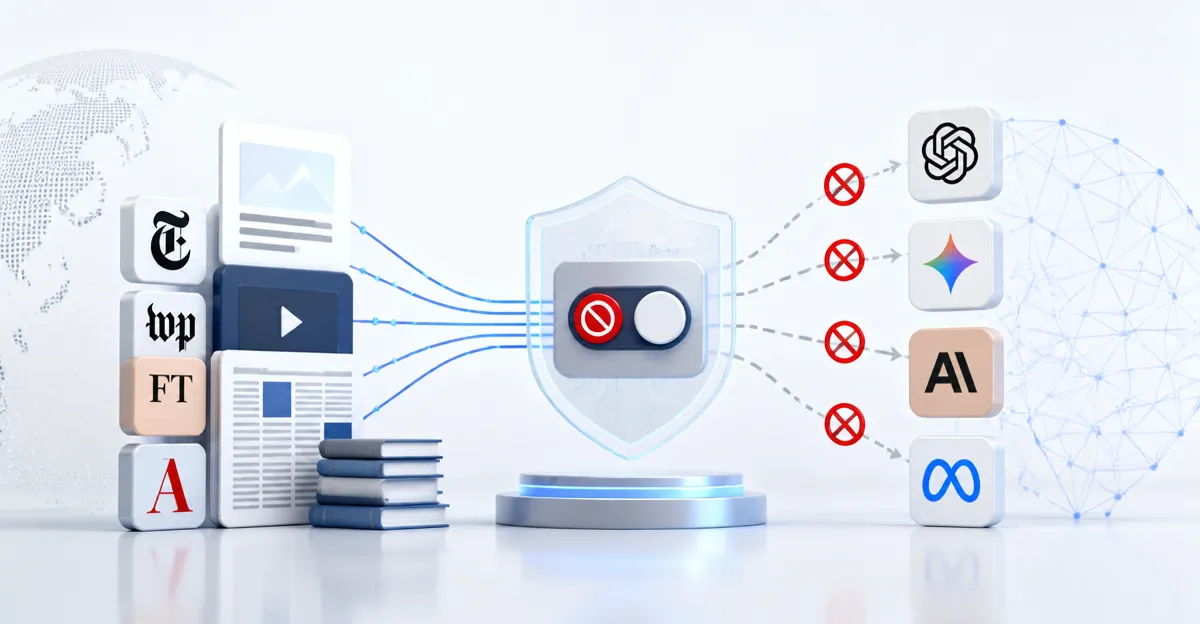
November 1, 2026, (Inside AI) — A single line of text in a website's robots.txt file could soon decide whether AI companies train on that content. A proposed standard called the policy token, introduced by Anthropic technical lead Kevin Kelley inside the Internet Engineering Task Force (IETF), would let publishers broadcast one opt-out signal to every major AI developer at once. OpenAI, Google, Microsoft, and Anthropic have said they will honor it. Meta has signaled support but has not committed to a date.
The token is not a new file format. It sits inside robots.txt, the decades-old convention that already tells search crawlers which pages they may index. Today, a publisher who wants to block AI training must configure separate controls for each provider, or rely on a crawler to respect a preference it may not read. The policy token collapses that work into one shared declaration. Anthropic says it has already adopted the signal. OpenAI plans to implement it in the coming months. Google and Microsoft expect support next year.
The gap between announcement and enforcement is the story. A standard only works if every major crawler honors it, and the largest holdout is Meta, whose crawlers feed models across Facebook and Instagram. Meta communications head Andy Stone framed the company's position as supportive but non-binding.
"We believe creating a common signal that conveys such preferences to multiple providers at once is an important step. And we look forward to working with other AI companies on the standards and their implementation across the industry," Stone said.
Read: Meta Deletes AI Scraping Clause After Expert Backlash
That language commits Meta to the idea, not the timeline. Until Meta names a date, publishers cannot treat the token as a guarantee. The IETF process itself adds another layer of uncertainty. A proposal becomes a standard only after working-group review, and adoption by four companies does not bind a fifth. The token's real test will be whether it survives contact with crawlers that operate outside the signatories, including smaller model developers and unaffiliated scrapers.
The backdrop is a multi-year fight over data. Publishers have sued AI developers over training on copyrighted work without permission or payment. The disputes intensified as AI crawlers multiplied, pulling pages for model training, retrieval, and grounding. Existing tools have limits. Cloudflare blocks AI crawlers by default for its customers. The Really Simple Licensing (RSL) standard lets publishers charge crawlers that visit their sites. Microsoft has added granular controls that separate AI training from AI grounding, the process of grounding a model in verified sources to reduce hallucinations. Google offers similar switches that do not affect search visibility.
What separates the policy token is breadth. It is a preference signal, not a payment mechanism. It does not let publishers negotiate a license or set a price. It only says no. That makes it cheap to deploy and easy to ignore. A publisher who wants compensation still needs a contract, and a crawler that ignores robots.txt already ignores the token. The standard's value lies in reducing the cost of compliance for companies that want to comply, and in creating a public record of who does.
The comparison to robots.txt is instructive. That protocol became a de facto norm because search engines competed on respecting it. AI companies now face a similar reputational calculation. A company that honors the token can claim good faith in copyright debates. A company that does not becomes a visible outlier. The token turns a private preference into a public test, and that may matter more than any enforcement mechanism.
For publishers, the practical effect depends on adoption speed. A site that adds the token today gets protection from Anthropic and, soon, OpenAI. Google and Microsoft arrive next year. Meta remains open-ended. The result is a partial shield, not a wall. Publishers will still need to monitor crawler behavior and keep separate controls for providers that lag. The token lowers the burden but does not remove it.
Read: Anthropic Bans AI Abuse as Big Tech Debates Machine Consciousness
The proposal also raises a question about scope. Robots.txt governs crawling, not training. A crawler that respects the token may still collect content for search indexing, and the line between indexing and training is blurry for models that learn from retrieval. The standard does not resolve that ambiguity. It only gives publishers a clearer way to state intent, and gives AI companies a clearer way to claim they listened.