November 21, 2026, (Inside AI) — Amazon Web Services has released a new agent skill that automates the setup and optimization of distributed key-value (KV) caching for self-hosted large language models (LLMs), claiming it can cut inference costs by up to 40% and time to first token (TTFT) by up to 80%. The skill, part of the Agent Toolkit for AWS, works with coding agents such as Kiro, Claude Code, and OpenAI Codex to guide users through evaluating, sizing, and deploying a shared cache tier on Amazon ElastiCache.
The move targets a growing pain point for enterprises that self-host LLMs on GPUs: redundant computation. When a user resumes a long conversation, the GPU often recomputes the entire history of key-value attention states, a process called prefill, because each server's local cache cannot hold or share that context. For applications like legal assistants or coding agents, where conversations can accumulate hundreds of thousands of tokens, this redundancy can add minutes of latency and inflate GPU costs.
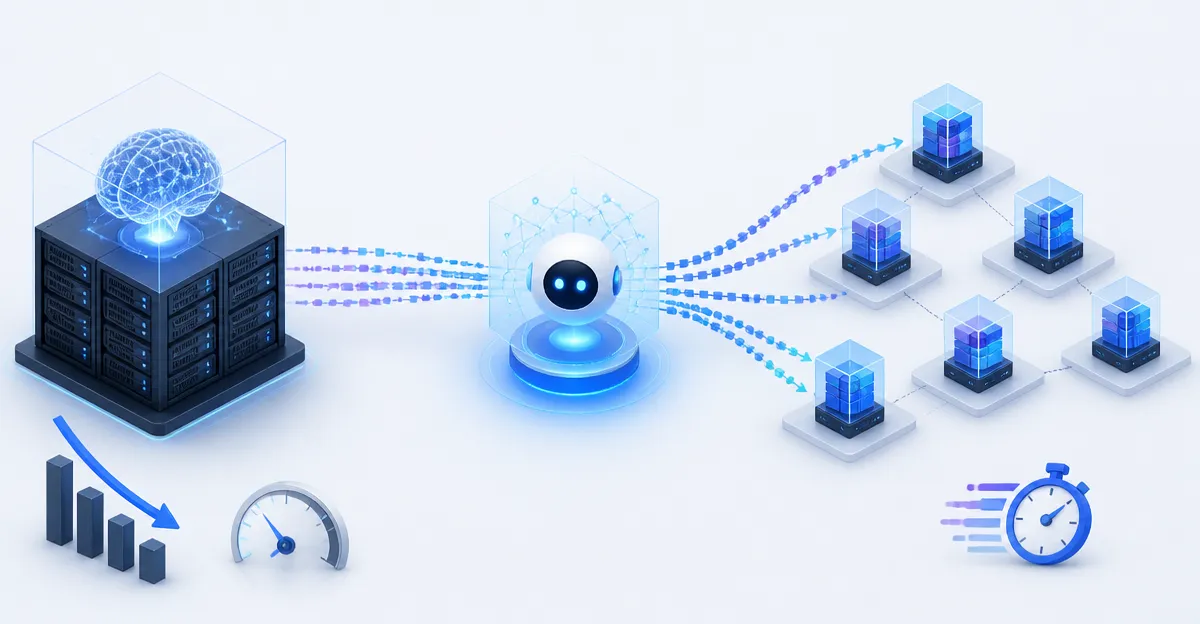
Distributed KV caching addresses this by extending GPU-local caches with a shared tier beside the GPU fleet. Any server can then reuse KV state for days, even across routing shifts or server failures. The new skill simplifies the complex process of estimating benefits, sizing the cache, and configuring inference servers.
Why A Skill For KV Caching?
The benefits of distributed KV caching vary widely depending on model, traffic patterns, and routing choices. Estimating them requires deep technical knowledge. AWS created a tool called KVTrace to provide close estimates from a user's own workload before deploying any infrastructure. The skill automates this evaluation and guides the coding agent through best practices.
Read: Amazon SageMaker AI Adds KV Cache-Aware Routing for Faster LLM Inference
First, it performs a fit check before any spend. The agent reads the GPU fleet with a read-only describe-instances call and counts Elastic Fabric Adapter (EFA) interfaces. It asks for engine, model, tensor-parallel size, KV data type, server price, and prompt repetition frequency. It stops and explains when something doesn't fit.
Second, it generates numbers from the user's workload. For short prompts, loading KV state can take longer than recomputing it. Above a certain prompt length, the read wins. The agent estimates savings with KVTrace and stops if they don't cover the cache's cost. Every number cites its source.
Third, it manages configuration across inference servers using the existing stack. The agent adds the LMCache connector to vLLM or SGLang engines, including vLLM workers under serving frameworks like llm-d and Ray Serve. It ensures all servers use the same KV ID mechanism and data type to avoid key mismatches.
Fourth, it implements best practices. Before production traffic, the agent empties local tiers and checks that two cache-loaded runs give the same output, because a layout mismatch can produce healthy hit counters and wrong answers. It seeks explicit approval for high-impact operations.
Prerequisites include a coding agent that supports Agent Skills, GPU instances that support EFA RDMA write such as p5, LMCache 0.5.8rc1 or later, vLLM 0.11.1 or later (or SGLang 0.5.13 or later), and ElastiCache for Valkey 9.1 or later on cache.i8ge.48xlarge nodes.
The skill supports four conversation flows: diagnosing slow first token, estimating savings, setting up a cache, and troubleshooting. In a diagnostic example, an agent identified cold prefill as the cause of 13-second TTFT for a legal assistant with 64K-token contexts. It checked for no-infrastructure fixes like enabling prefix caching, identified tenant isolation constraints, and asked for model and TP size to estimate cache size.
Read: AWS Brings NVIDIA Dynamo to SageMaker HyperPod for Multi-Node LLM Inference
In a savings estimation flow, the agent looked up GPU and cache node prices, derived prefill rate and KV size from benchmarks, and recommended two cache.i8ge.48xlarge nodes for an 8-instance p5 fleet serving 64,000-token prompts. It presented scenarios because the user didn't provide a cache hit rate, and recommended a KVTrace run to measure it.
In a setup flow, the agent created a security group with EFA permissions, a Valkey 9.1 cluster with caching eviction policies, and an LMCache user with password in AWS Secrets Manager. It started one LMCache server per GPU server and verified RDMA-based KV state loading.
In a troubleshooting flow, the agent reasoned from symptoms (rdma_write_errors climbing) to a security group blocking EFA traffic between its own members, and provided commands to fix the rule.
The release underscores a broader shift: as enterprises move from experimenting with LLMs to deploying them in production, operational efficiency becomes paramount. Distributed caching is one lever; others include quantization, speculative decoding, and better batching. AWS's skill approach lowers the barrier to adopting advanced caching by embedding expert knowledge into coding agents.
However, the skill requires specific hardware and software versions, which may limit immediate adoption. Also, the 40% cost and 80% latency reductions are best-case figures; actual gains depend on workload characteristics. AWS advises using KVTrace to validate benefits before committing to infrastructure.
The skill is available now in the Agent Toolkit for AWS. Users can get started by describing their problem to a supported coding agent or by asking it to cut costs and latency on their GPU fleet.

If a research paper dropped this week, Mahesh has already read it. He covers AI tools and vibe coding for builders who need to know what is worth their time and what is not.