June 25, 2026, (Inside AI) — A new pattern in retrieval-augmented generation (RAG) systems lets a single large language model (LLM) call rank document candidates with explicit reasons, replacing traditional score fusion. The approach, detailed in a recent Towards Data Science article, introduces the “arbiter”—an LLM that decides which retrieved passages actually matter, and why.
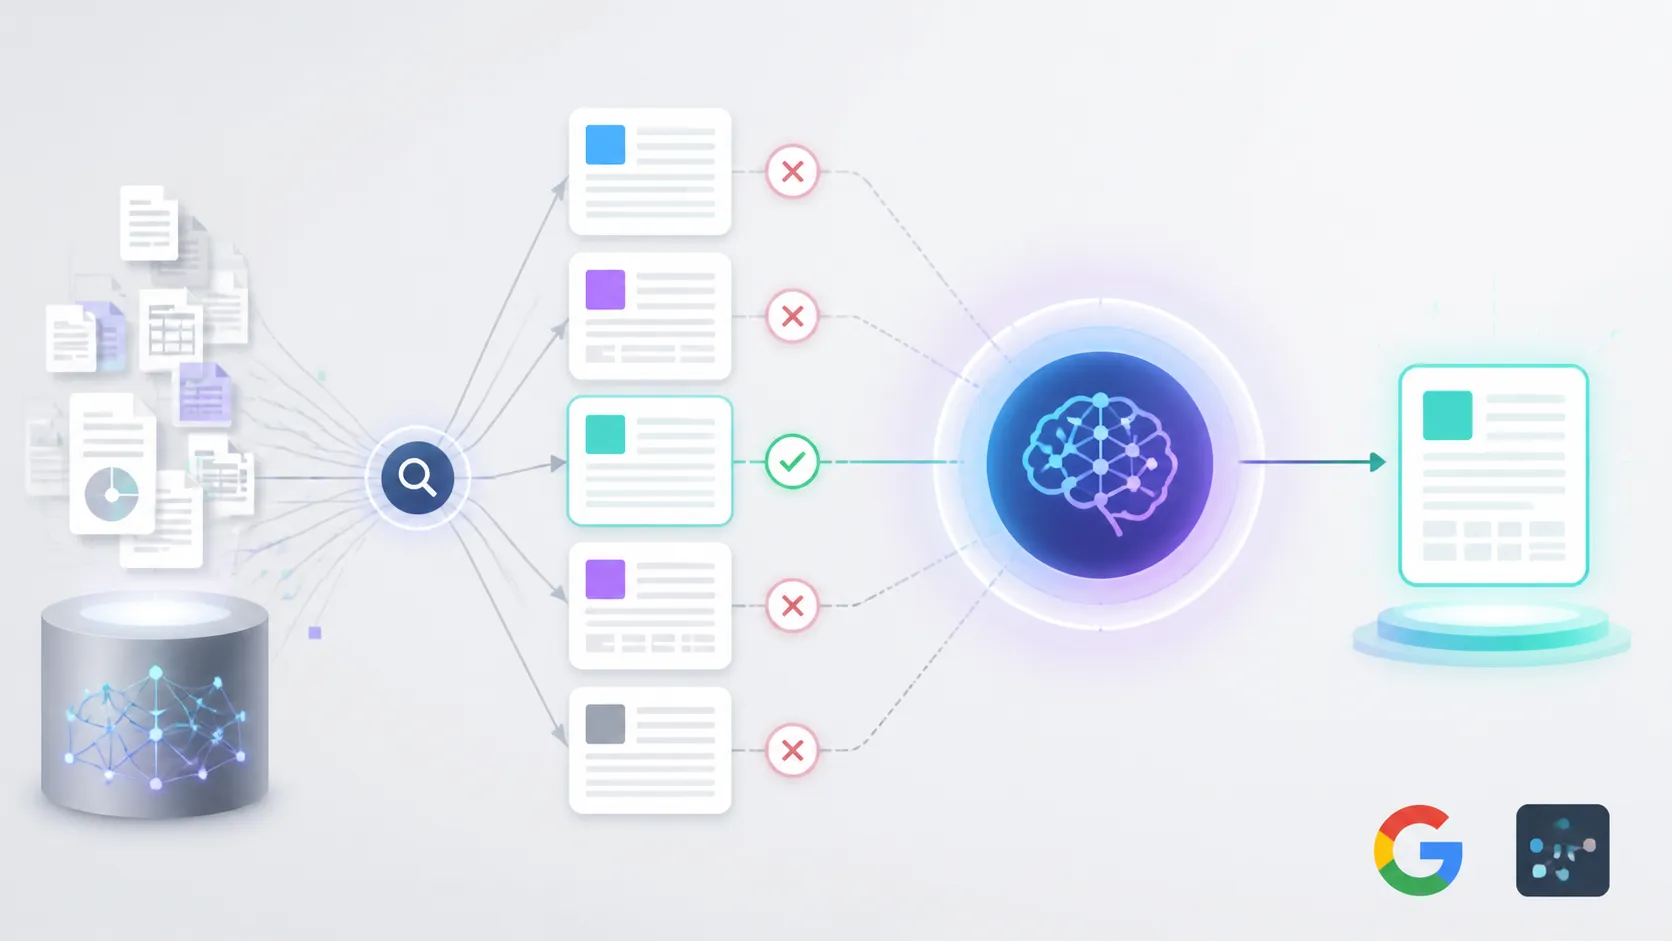
The arbiter sits at the end of a three-stage retrieval pipeline. It receives a structured brief of candidates from keyword, embedding, and table-of-contents (TOC) detectors. Instead of merging scores with Reciprocal Rank Fusion (RRF), the LLM reads each candidate’s anchor, matched keywords, surrounding context, and section, then assigns a role: primary, supporting, tangential, or dropped. Every decision comes with a plain-text reason for audit trails.
“Detectors propose, the arbiter decides,” the article states. This single-call design preserves the signal that score fusion discards—why a method ranked a candidate. A TOC match on a section title is a structural signal; a high cosine similarity without keyword overlap is likely noise. RRF turns both into the same rank number, losing that distinction.
The arbiter also flags contradictions between passages, a common need in contracts with amendments. Its output is a typed JSON object that generation can consume directly, with no further retrieval queries. The approach was demonstrated on the “Attention Is All You Need” paper, where a question about positional encoding returned two primary candidates from the TOC-hit section, while two keyword-only hits were correctly dropped as contextual noise.
Read: Tool Calling Transforms AI Agents
Embeddings play a supporting role in this framework. The article argues they dilute high-signal tokens, cannot distinguish related concepts like “premium” and “deductible,” and lack document structure awareness. Keyword and TOC methods are preferred for enterprise documents, with embeddings reserved for vocabulary mismatch or conceptual queries. A production ablation showed a 23-point gap between embeddings-only and the full method mix.
The system also handles “not found” reliably. Keyword retrieval proves absence because a zero hit across an exhaustive dictionary is defensible evidence. Embedding retrieval always returns top-k results with continuous scores, making absence uncertain. “No answer beats a wrong one” in compliance, legal, and finance contexts, the article warns.
The retrieval output is a unified JSON per document-question pair, carrying both anchor (precise citation) and context (surrounding paragraph). This artifact is replayable, versionable, and auditable. A decision tree dispatcher selects which detectors to run per question, avoiding hard-coded strategies that produce noisier candidates.
Read: Decay Engine Outperforms Recency Windows
The arbiter pattern is part of a broader enterprise RAG series. It builds on anchor detection and question parsing, and feeds into a generation brick that extracts answers, formats citations, and refuses to invent when evidence is absent. The full pipeline is available in a minimal runnable example.

Shamil has a low tolerance for AI that only works in controlled demos. He covers agentic systems and generative AI with the skepticism of someone who has seen too many “revolutionary” tools quietly disappear six months after launch.