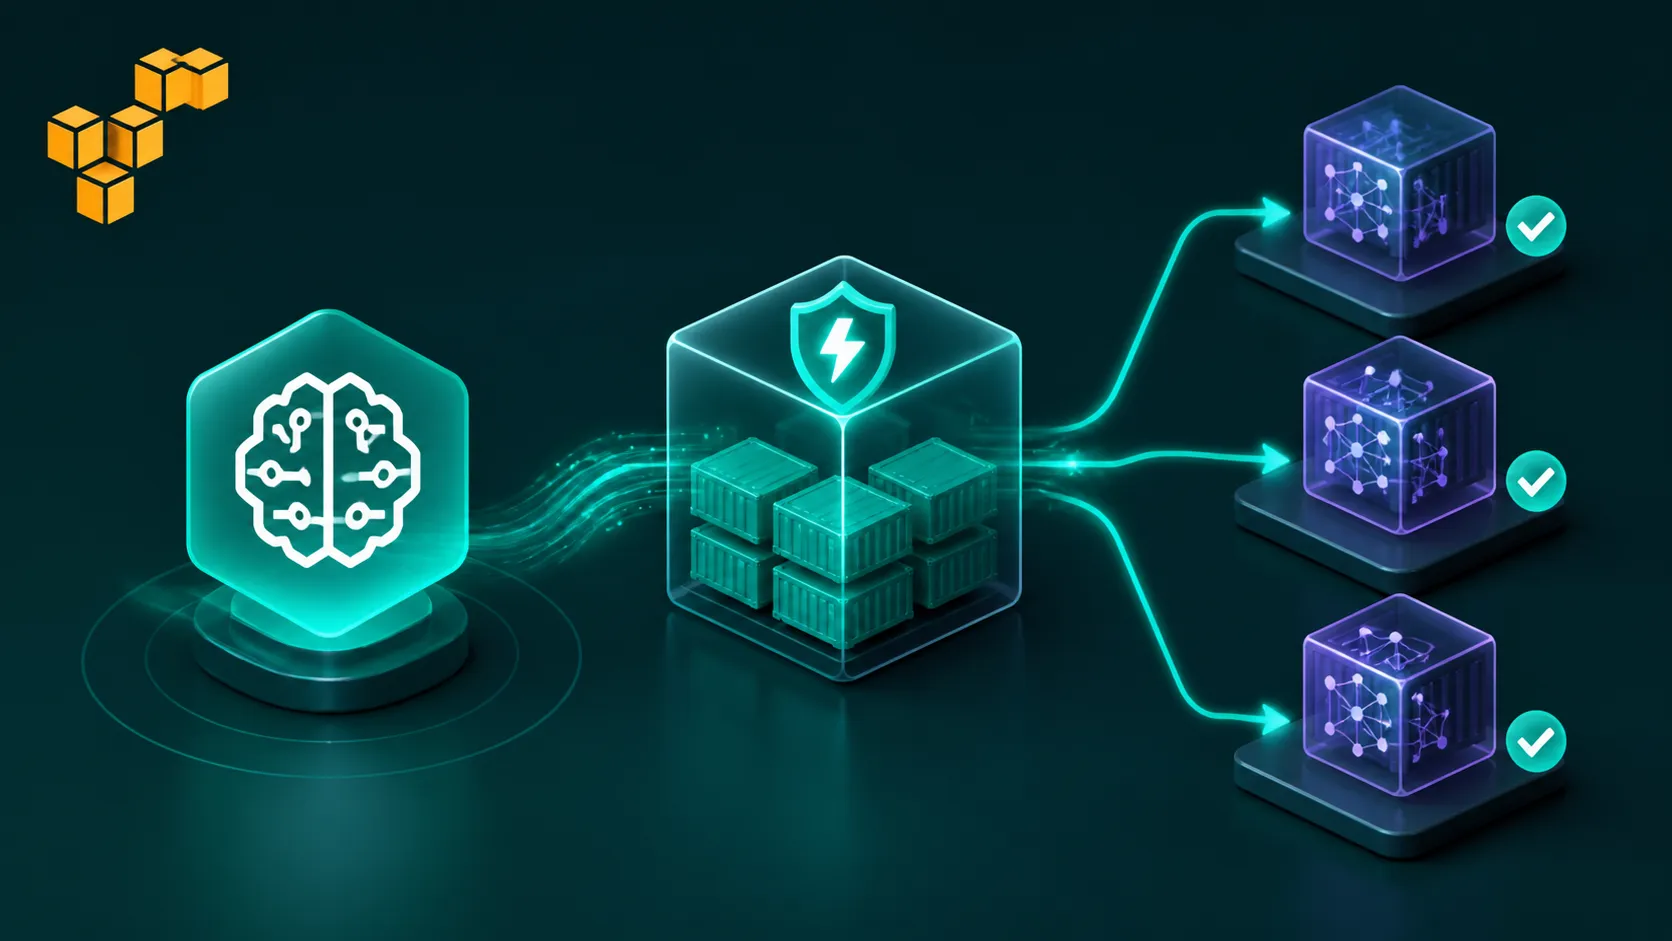
June 17, 2026, (Inside AI) — Amazon SageMaker AI now offers container image caching for inference, cutting end-to-end latency by up to 2x during scale-out events. The feature eliminates container image download time when new instances launch, addressing a key bottleneck for generative AI workloads.
Why Container Downloads Stall AI Scaling
When traffic spikes force new instances to spin up, SageMaker AI must pull container images from Amazon Elastic Container Registry. For large models, these images can exceed 17 GB compressed. That download competes with model artifact fetching, dragging out cold starts.
Amazon previously introduced sub-minute CloudWatch metrics and data caching on existing instances. But those fixes helped only when reusing warm instances. Container caching now targets the harder problem: brand-new instance launches.
How the Cache Slashes Startup Time
In tests with the Qwen3-8B model on an ml.g6.2xlarge instance using the LMI container, end-to-end startup dropped from 525 seconds to 258 seconds. That is a 51% improvement. The cache removes the image pull step and network contention.
If a cached image is unavailable, SageMaker AI falls back to Amazon ECR automatically. Scaling never blocks. The cache stores each unique container image per endpoint, including custom images. No container modifications are needed.
Security and Multi-Model Deployments
Each cache is dedicated to a single customer endpoint. It is not shared across accounts or endpoints. When you delete an endpoint, the associated cache is purged. This preserves the strict tenant isolation SageMaker AI already enforces.
For inference component-based endpoints, the cache stores every distinct image referenced. When scaling adds new instances because existing ones lack capacity, container caching kicks in.
Stacking Optimizations for Maximum Speed
Amazon now offers three complementary scaling optimizations. Sub-minute metrics detect demand 6x faster. Data caching on existing instances removes image and model download latency. Container caching eliminates image pulls on new instances.
Together, they transform scaling from minutes of cold-start latency to rapid, predictable responses. Early access customers saw improvements that vary by instance type, container size, and model size.
Availability and Next Steps
Container caching is available in all commercial AWS Regions where SageMaker AI inference operates. It supports accelerator instance types and any Amazon ECR image. The feature activates automatically on supported endpoints.
Amazon says it will continue investing in reducing scaling latency further. For now, generative AI applications can handle traffic spikes with lower latency and higher availability.