June 17, 2026, (Inside AI) — Amazon Web Services has open-sourced Parallel-EAGLE (P-EAGLE), a new method that makes large language model inference faster by generating multiple draft tokens at once instead of one by one. The technique is now natively available in Amazon SageMaker JumpStart, letting developers deploy accelerated models with a single click.
The Bottleneck in Current Speed Boosts
Speculative decoding speeds up LLMs by using a small draft model to guess upcoming tokens, which the main model then checks in parallel. But frameworks like EAGLE-3 still hit a wall: they produce draft tokens sequentially. Each guess depends on the previous one, so making K candidates needs K forward passes, piling on latency.
EAGLE-3 improved accuracy by predicting tokens directly and mixing hidden states from several target model layers. Yet the deeper you speculate, the more overhead you add, eating into the speed gains.
How P-EAGLE Breaks the Chain
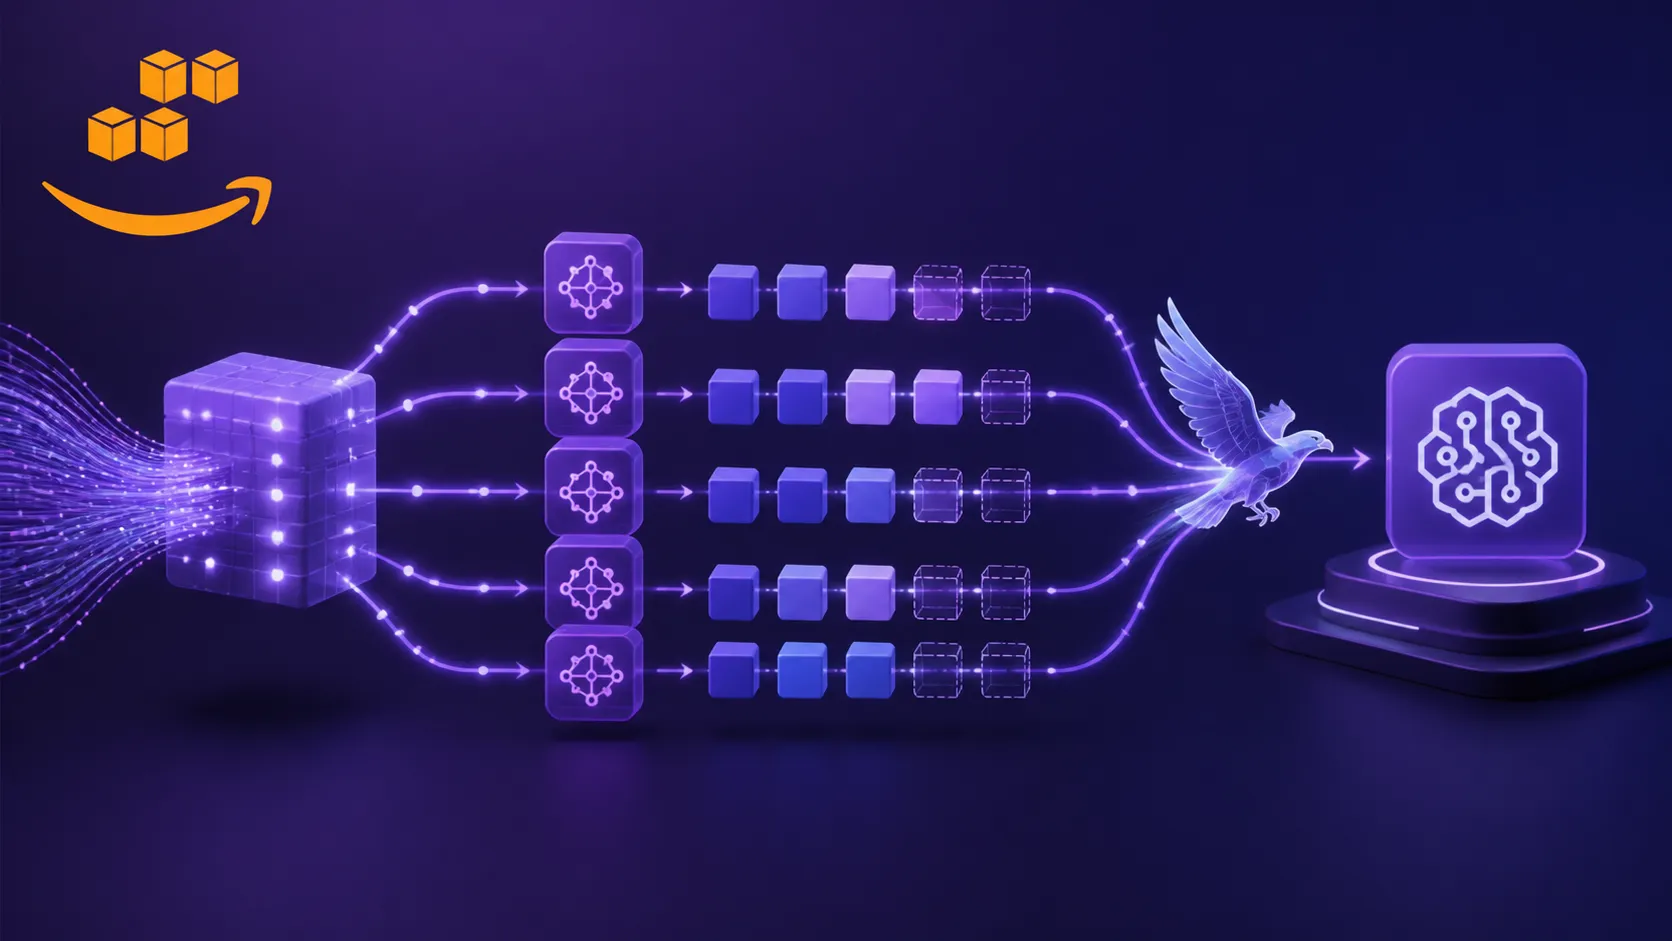
P-EAGLE, invented by AWS, eliminates this sequential dependency. It predicts all draft tokens in a single forward pass using learnable placeholders—a mask token embedding and a shared hidden state—that stand in for missing inputs at future positions. This decouples draft count from forward passes, allowing deeper speculation without extra latency.
Read: Amazon SageMaker AI Cuts Generative AI Scaling Time by Half with Container Caching
In benchmarks on NVIDIA B200 GPUs with FP8 quantization, P-EAGLE delivered up to a 1.69x throughput speedup over EAGLE-3. Gains held even under high concurrency, with peak performance at K=7 draft tokens.
One-Click Deployment in SageMaker JumpStart
Amazon SageMaker JumpStart now supports P-EAGLE for popular open-weight models like Qwen3-Coder-30B-A3B-Instruct. Users simply select a model, verify the pre-configured speculative settings, and deploy. The environment variable SM_VLLM_SPECULATIVE_CONFIG activates the parallel drafter, with a parameter controlling how many tokens are drafted per pass.
No manual training or custom containers are needed. The managed service handles provisioning, model artifacts, and the vLLM inference server, making accelerated endpoints ready in minutes.
Real-World Performance and Design
Live tests on ml.g7e.2xlarge instances showed P-EAGLE with K=3 outpacing standard inference in tokens per second. The drafter uses only 4 transformer layers—about 2–5% of target model parameters—keeping overhead low. Training supports sequences up to 20,000 tokens, preventing the acceptance rate drops seen with shorter-context methods.
Because the target model verifies all drafts, output quality matches the original model exactly. This makes P-EAGLE a practical choice for production workloads where speed must not compromise accuracy.
What’s Next for Faster Inference
Read: AWS SageMaker AI Adds Serverless Fine-Tuning for Google Gemma 4 Models
P-EAGLE shifts speculative decoding from an iterative to a parallel process, removing the linear latency cost of deeper speculation. With SageMaker JumpStart integration, developers can now deploy these optimized models quickly. For those wanting custom heads, SageMaker AI also supports training EAGLE heads on proprietary data, a feature launched last year.